Video · 38 seconds · no sound
Watch a reading-order repair: two columns rebuilt as one
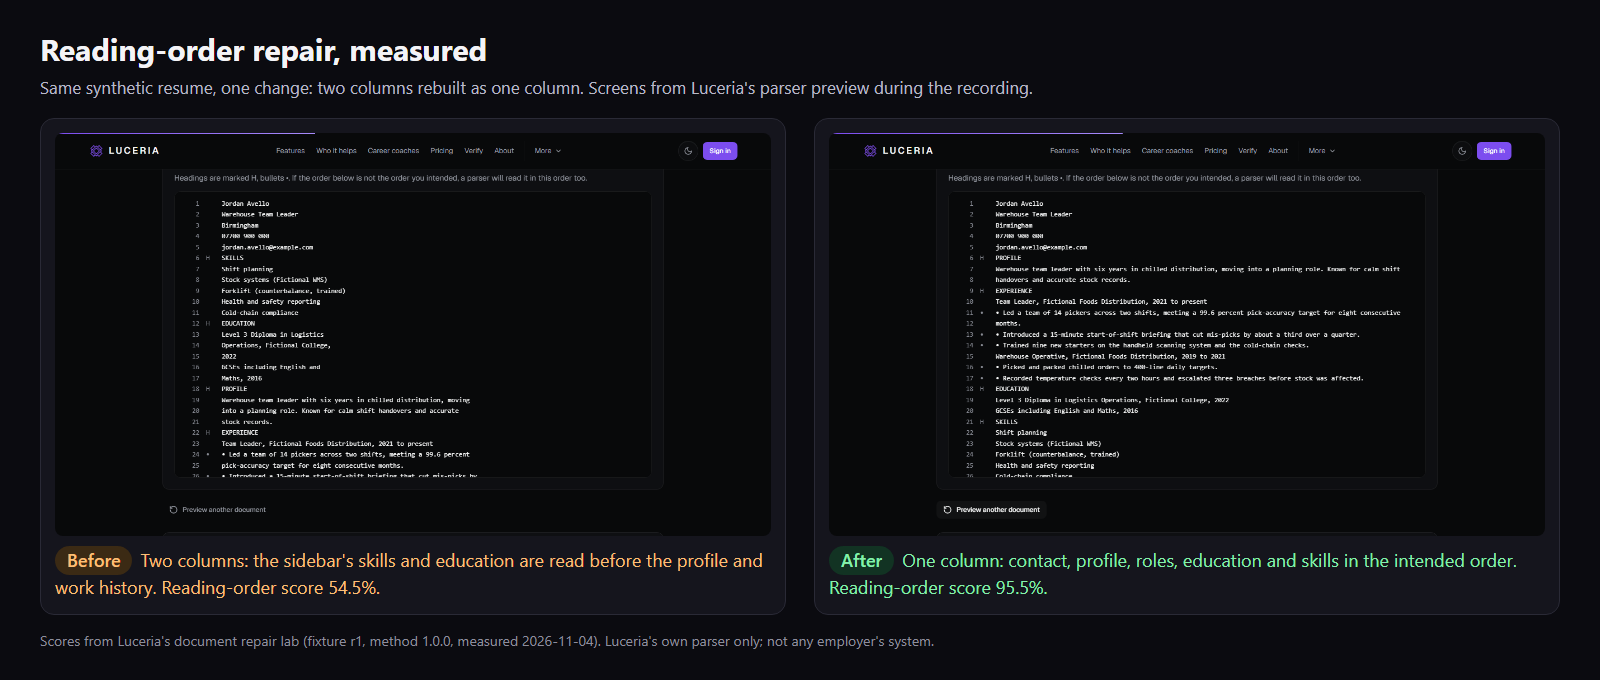
Luceria's free parser preview reads a synthetic two-column resume from the document repair lab. Its layout check flags nothing, but the extracted lines show the sidebar's skills and education read before the profile and work history. The same resume rebuilt as one column reads in the intended order.
What happens in the video
The video has no speech or sound. This is a complete account of what appears on screen; the same notes are the step-notes track in the player.
- 0:01–0:06Luceria's free parser preview: it shows what Luceria's own parser reads from a PDF or Word file, in the order it reads it.
- 0:06–0:10Step 1: choose the lab's synthetic two-column PDF (fixture r1-before). The preview reads it in the browser; the file is not sent anywhere.
- 0:10–0:14The preview accepts the file. Its layout check finds no artefact here and warns that two columns do not always leave one, so the problem shows only in the order of the extracted lines.
- 0:14–0:21Step 2: the extracted lines. In the two-column file the sidebar's skills and education are read before the profile and work history, so the sections come out of order.
- 0:21–0:23Step 3: preview the repaired file (fixture r1-after), the same content rebuilt as one column.
- 0:23–0:29The repaired file reads in the intended order: name and contact, profile, each role with its own bullets, then education and skills.
- 0:29–0:33The layout check reported no artefact for either file: the difference is the order of the lines. The lab measured this repair: reading-order score 54.5% before, 95.5% after.
Before and after
How this was recorded
- Recorded on a local production build of Luceria with Playwright's screen recorder in headless Chromium, at 1280 by 720, with no audio.
- Inputs are the document repair lab's synthetic fixtures r1-before-two-column.pdf and r1-after-single-column.pdf. No real person's document appears.
- Every result on screen is what the parser preview produced during the recording; nothing was edited afterwards. Optional cookies were declined at the start so the banner does not cover the screen.
- The scores on the annotated still come from the lab's published results file, not from the recording.
Related
- Document repair lab: method, fixtures and results
- Download the two-column fixture (PDF)
- Download the one-column fixture (PDF)
Recorded 5 November 2026. Synthetic documents only; Luceria’s own parser, not any employer’s system.